Quickstart
This page takes you from zero to a completed SDDP study in three commands using the
built-in 1dtoy template. The template models a single-bus hydrothermal system with
one hydro plant and two thermal units over a 4-stage finite planning horizon — small
enough to run in seconds, complete enough to demonstrate every stage of the workflow.
If you have not installed Novomodelo yet, start with Installation.
Step 1: Scaffold a Case Directory
Section titled “Step 1: Scaffold a Case Directory”novomodelo init --template 1dtoy my_first_studyNovomodelo writes 11 input files into a new my_first_study/ directory and prints a
summary to stderr:
 ╺━━━━━━━━━╻● ╺━━━━━━━━━╻●⚡  NOVOMODELO v0.18.0 ╺━━━━━━━━━╻●   Power systems in Rust
Created my_first_study case directory from template '1dtoy':
  ✔ config.json  Algorithm configuration: training (forward passes, stopping rules) and simulation settings  ✔ initial_conditions.json  Initial reservoir storage volumes for each hydro plant at the start of the planning horizon  ✔ penalties.json  Global penalty costs for constraint violations (deficit, excess, spillage, storage bounds, etc.)  ✔ stages.json  Planning horizon definition: policy graph type, discount rate, stage dates, time blocks, and scenario counts  ✔ system/buses.json  Electrical bus definitions with deficit cost segments  ✔ system/hydros.json  Hydro plant definitions: reservoir bounds, outflow limits, turbine model, and generation limits  ✔ system/hydro_production_models.json  Per-(hydro, stage) production-model configuration carrying the productivity coefficient  ✔ system/lines.json  Transmission line definitions (empty in this single-bus example)  ✔ system/thermals.json  Thermal plant definitions with piecewise cost segments and generation bounds  ✔ scenarios/inflow_seasonal_stats.parquet  Seasonal PAR(p) statistics for hydro inflow scenario generation (mean, std, lag correlations)  ✔ scenarios/load_seasonal_stats.parquet  Seasonal PAR(p) statistics for electrical load scenario generation (mean, std, lag correlations)
Next steps:  -> novomodelo validate my_first_study  -> novomodelo run my_first_study --output my_first_study/results
The directory structure is:
my_first_study/ config.json initial_conditions.json penalties.json stages.json system/ buses.json hydros.json hydro_production_models.json lines.json thermals.json scenarios/ inflow_seasonal_stats.parquet load_seasonal_stats.parquetStep 2: Validate the Case
Section titled “Step 2: Validate the Case”novomodelo validate my_first_studyThe validation pipeline checks every layer — schema, references, physical
feasibility and stochastic consistency — then
builds the study as novomodelo run does and checks any policy the run would load,
without solving an LP, and prints a single line of entity counts on success:
Valid case: 1 buses, 1 hydros, 2 thermals, 0 linesThat is the whole output for a warning-free case; a case that raises warnings
adds a Validation: 0 errors, N warnings in <dir> summary and one warning:
line per finding. If any layer fails, Novomodelo prints a
Validation: N errors, 0 warnings in <dir> summary followed by each error
prefixed with error:, and exits non-zero: 1 for a refused case, 2 for a declared opening-tree file that is absent
(see CLI Reference — Exit Codes). The 1dtoy template always passes
validation.
Step 3: Run the Study
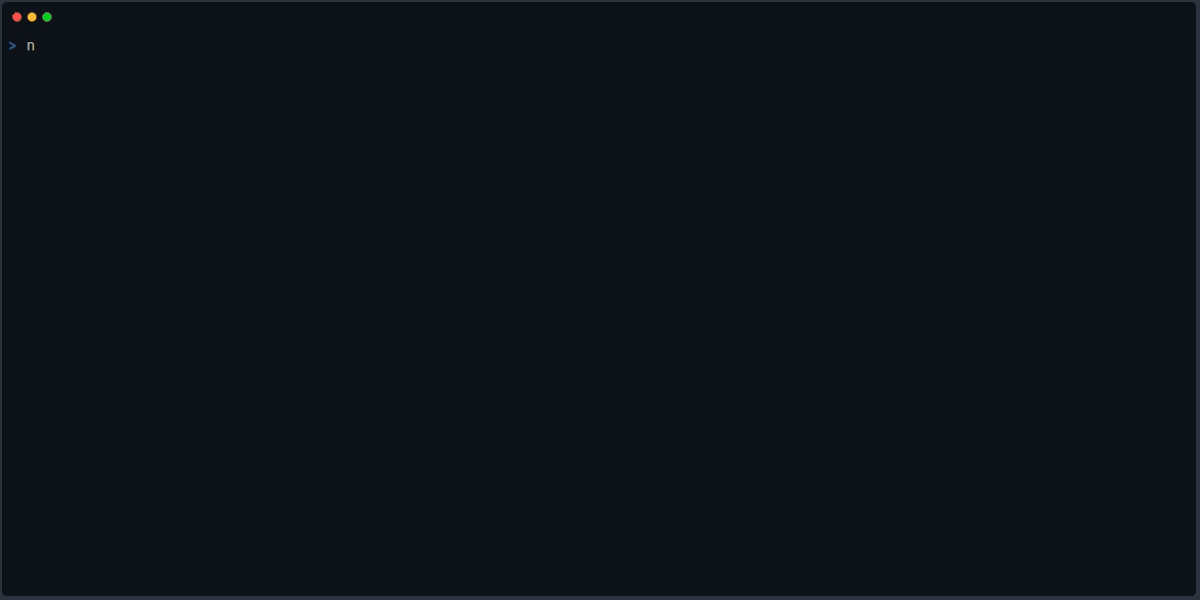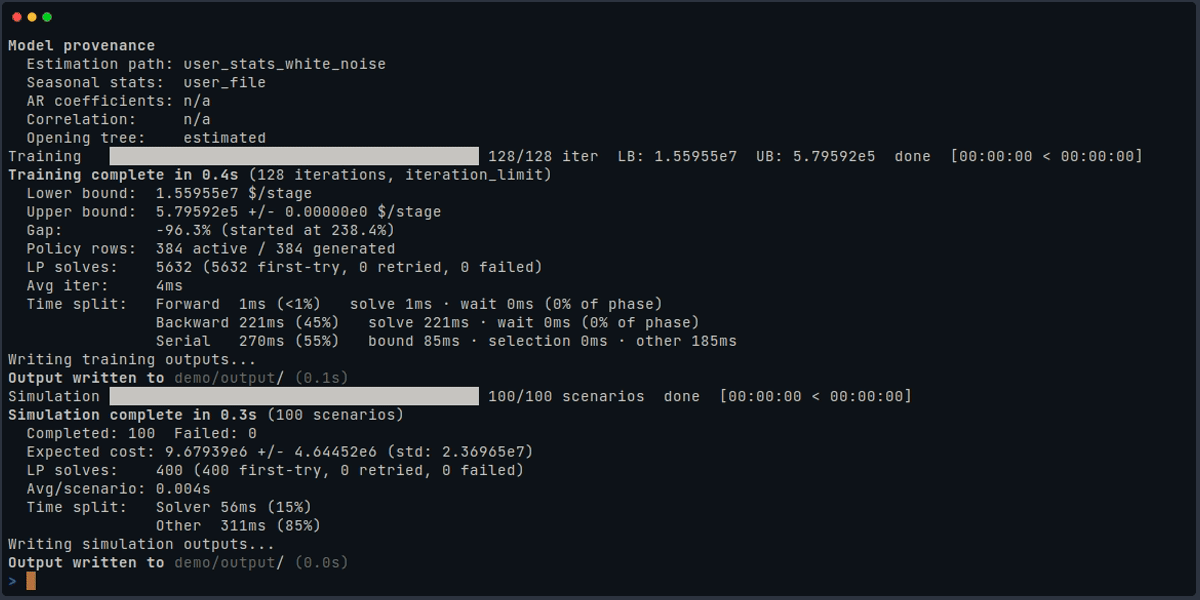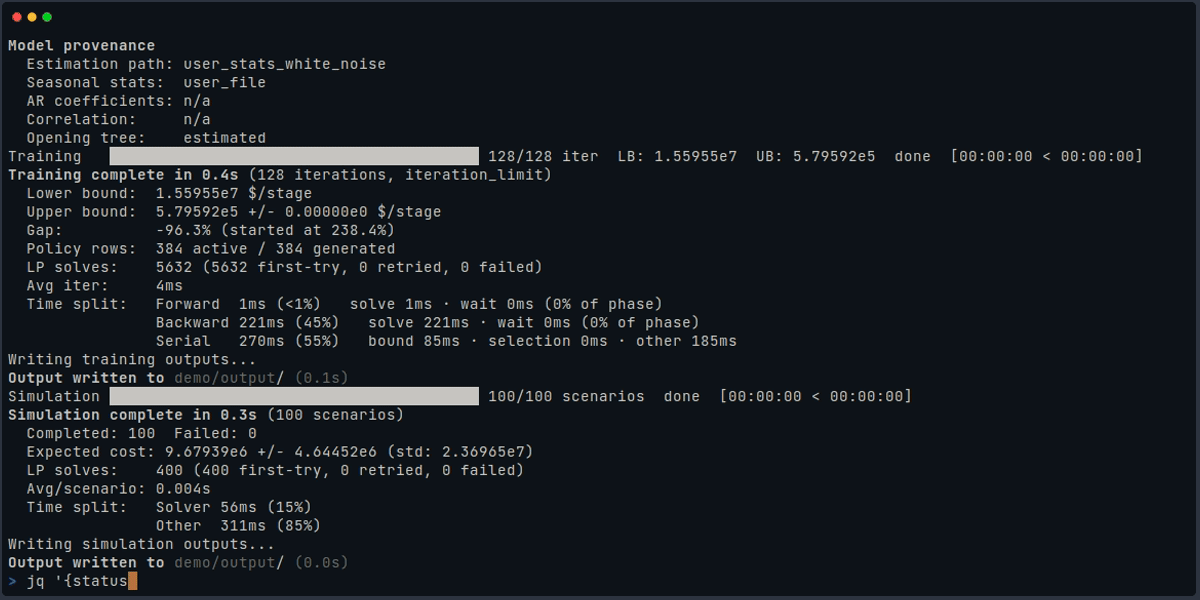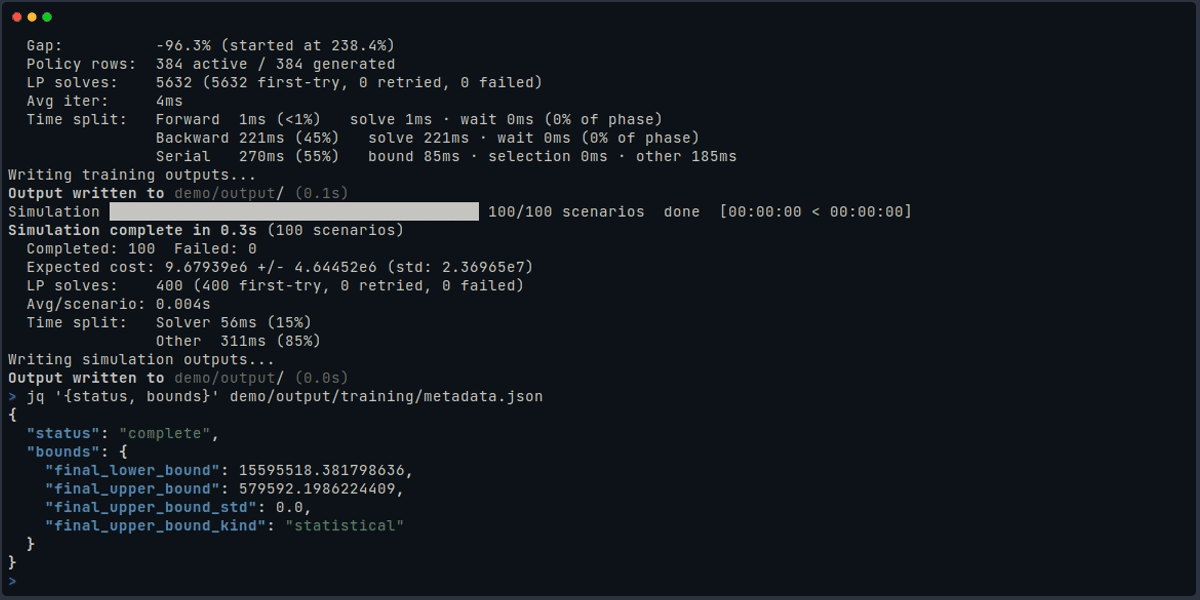
Section titled “Step 3: Run the Study”novomodelo run my_first_study --output my_first_study/resultsNovomodelo runs the SDDP training loop (128 iterations, 1 forward pass each) followed by
a simulation pass (100 scenarios). Output is written to my_first_study/results/.
The banner, an execution/setup header, and progress bars are printed to stderr;
once the progress bars finish, the rest of stderr is the post-run summary:
Training complete in 0.4s (128 iterations, iteration_limit) Lower bound: 1.55955e7 $/stage Upper bound: 5.79592e5 +/- 0.00000e0 $/stage Gap: -96.3% (started at 238.4%) Policy rows: 384 active / 384 generated LP solves: 5632 (5632 first-try, 0 retried, 0 failed) Avg iter: 3ms Time split: Forward 3ms (<1%) solve 3ms · wait 0ms (0% of phase) Backward 186ms (42%) solve 186ms · wait 0ms (0% of phase) Serial 249ms (57%) bound 53ms · selection 0ms · other 196msWriting training outputs...Output written to my_first_study/results/ (0.0s)Simulation starting... (100 scenarios across 1 ranks × 1 threads)Simulation complete in 0.1s (100 scenarios) Completed: 100 Failed: 0 Expected cost: 9.67939e6 +/- 4.64452e6 (std: 2.36965e7) LP solves: 400 (400 first-try, 0 retried, 0 failed) Avg/scenario: 0.002s Time split: Solver 53ms (27%) Other 144ms (73%)Writing simulation outputs...Output written to my_first_study/results/ (0.0s)The results directory contains training convergence data, a FlatBuffers policy
checkpoint, and Hive-partitioned Parquet files for simulation dispatch results.
This is what the 1dtoy template produces:
my_first_study/results/ training/ _SUCCESS metadata.json convergence.parquet hydro_models.json model_provenance.json scaling_report.json dictionaries/ solver/ timing/ policy/ manifest.bin cuts/ 000.bin ... 003.bin basis/ 000.bin ... 003.bin simulation/ _SUCCESS metadata.json paths.parquet scenario_summary.parquet buses/ costs/ hydro_bus_generation/ hydros/ inflow_lags/ solver/ thermals/The tree is template-specific. policy/basis/ holds a file per stage only when
training produced a warm-start basis for that stage (the directory itself is
always created), and cases with other entities add further simulation
partitions — for example pumping_stations/, contracts/, in_transit/, and
generic-constraint violations/. See Output Format
for the authoritative, conditional schema of every file.
What You Just Ran
Section titled “What You Just Ran”The 1dtoy case has one bus whose unserved demand (deficit) costs 7500 $/MWh. The hydro plant
UHE1 has a 1000 hm³ reservoir that starts at 83.222 hm³ and turbines up to 50 m³/s at
1 MW per m³/s. The thermal plants UTE1 and UTE2 provide 15 MW each, at 5 and 10 $/MWh.
Demand is a constant 75 MW.
The horizon has four monthly stages, stage 1 (January 2024) to stage 4 (April 2024), with
one load block each. Every stage draws ten inflow openings (num_openings) from the
seasonal statistics in scenarios/ (mean 40 m³/s), with no autoregressive lags. The annual
discount rate is 0.12.
Configuration files and outputs identify the same stages by their declared stage_id,
0 to 3 here; the policy files 000.bin … 003.bin are numbered from 0 in stage order.
See Stage Indexing.
For an SDDP iteration worked by hand on a one-reservoir system, see the Toy Single-Reservoir SDDP Walkthrough; the Toy Four-Reservoir SDDP Walkthrough extends it to four reservoirs.
Reading the Summary
Section titled “Reading the Summary”- Units. The lower bound, the upper bound and the expected cost are each an expected
total for the whole horizon: the four stages’ costs, discounted to the start of stage 1,
in the currency of the case’s costs. Despite the
$/stagelabel, none of them is a per-stage value. - Band. The number after
+/-on theUpper boundline is the standard deviation of that iteration’s forward-pass costs. Withforward_passes: 1there is one cost per iteration, so the spread is zero and the line prints+/- 0.00000e0. On theExpected costline,+/-is the half-width of the 95 % confidence interval for the mean andstdis the standard deviation of the scenario costs. - Negative gap. The upper bound is the cost of the iteration’s one sampled trajectory. The optimality gap is that cost minus the lower bound, relative to the lower bound, so a trajectory cheaper than the lower bound gives a negative gap. Most trajectories of this case cost about 6e5; the ones that run short of water pay the deficit cost, up to about 1.5e8 across the 128 iterations. The last iteration drew a cheap one. With sampled forward passes the gap is an estimate, not a guarantee.
- Lower bound above the simulated mean. The
lower bound is the first stage’s expected
value over its ten openings with the trained cuts. The expected cost is the mean of 100
scenarios drawn from the same ten openings per stage. Their standard deviation
(2.36965e7) is more than twice the mean: most scenarios are cheap and a few are very
expensive, so a 100-scenario mean often falls below the expected cost it estimates,
and the lower bound never exceeds that expected cost. A larger
simulation.selection.num_scenariosnarrows the interval. - Reproducibility. The bounds, the gap, the expected cost and the policy-row and
LP-solve counts are the same on every run; only the timings vary with the machine. The
ten inflow openings and the in-sample draws are seeded by
training.tree_seed(unset in the template, so the default 42 applies).training.scenario_source.seedseeds only out-of-sample draws, which this case does not use; Seed resolution describes both seeds. Changingtraining.tree_seed, the stopping rule orforward_passeschanges the bounds. The complete summary format, including theTime splitblock, is documented in CLI Reference — Output format.
Step 4: Read the Results
Section titled “Step 4: Read the Results”The convergence history and the simulation costs are plain Parquet files. Install
polars and matplotlib with
pip install polars matplotlib, then run the snippets from the directory that holds
my_first_study/. The first prints the last three iterations of
training/convergence.parquet and summarises the per-scenario costs in
simulation/costs/:
import polars as pl
conv = pl.read_parquet("my_first_study/results/training/convergence.parquet")print(conv.select("iteration", "lower_bound", "upper_bound", "gap_percent").tail(3))
costs = pl.read_parquet("my_first_study/results/simulation/costs/")per_scenario = costs.group_by("scenario_id").agg(    (pl.col("discount_factor") * pl.col("immediate_cost")).sum().alias("cost"))print(per_scenario.select(    pl.col("cost").mean().alias("mean"),    pl.col("cost").median().alias("median"),    pl.col("cost").max().alias("max"),))
shape: (3, 4)┌───────────┬─────────────┬───────────────┬─────────────┐│ iteration ┆ lower_bound ┆ upper_bound ┆ gap_percent ││ --- ┆ --- ┆ --- ┆ --- ││ i32 ┆ f64 ┆ f64 ┆ f64 │╞═══════════╪═════════════╪═══════════════╪═════════════╡│ 126 ┆ 1.5596e7 ┆ 615923.497494 ┆ -96.050638 ││ 127 ┆ 1.5596e7 ┆ 615923.497494 ┆ -96.050638 ││ 128 ┆ 1.5596e7 ┆ 579592.198622 ┆ -96.283598 │└───────────┴─────────────┴───────────────┴─────────────┘shape: (1, 3)┌──────────┬───────────────┬──────────┐│ mean ┆ median ┆ max ││ --- ┆ --- ┆ --- ││ f64 ┆ f64 ┆ f64 │╞══════════╪═══════════════╪══════════╡│ 9.6794e6 ┆ 615923.497494 ┆ 1.2349e8 │└──────────┴───────────────┴──────────┘The last row repeats the summary’s bounds and gap, and the mean is the summary’s expected
cost; the median shows that most scenarios are cheap and the maximum that a few are very
expensive, the long tail described in Reading the Summary. A
scenario’s cost in this case is the sum over stages of discount_factor * immediate_cost; total_cost
also carries the future-cost estimate, so summing it does not reproduce the expected cost.
The second snippet plots both bounds against the iteration number. It writes
convergence.png to the working directory, so it runs without a display:
import matplotlibmatplotlib.use("Agg")import matplotlib.pyplot as pltimport polars as pl
conv = pl.read_parquet("my_first_study/results/training/convergence.parquet")fig, ax = plt.subplots()ax.plot(conv["iteration"], conv["lower_bound"], label="lower bound")ax.plot(conv["iteration"], conv["upper_bound"], label="upper bound (one forward pass)")ax.set_yscale("log")ax.set_xlabel("iteration")ax.set_ylabel("expected cost")ax.legend()fig.savefig("convergence.png")print("saved convergence.png")
saved convergence.pngIn convergence.png the lower bound rises from 5.06e6 and flattens near 1.56e7, while the
upper bound of a single forward pass sits near 6e5 in most iterations, with spikes up to 1.51e8, on the
logarithmic axis.
Convergence & Diagnostics describes every output file, and the Python Quickstart runs and reads the same study from Python.
Step 5: Reduce the Sampling Noise
Section titled “Step 5: Reduce the Sampling Noise”The upper bound in Step 3 comes from one forward pass per iteration and the expected cost
from 100 scenarios, so both are noisy estimates. Two keys of config.json control that
noise: training.selection.forward_passes, the number of trajectories sampled in each
iteration, and simulation.selection.num_scenarios, the number of simulated scenarios.
Set these two values in my_first_study/config.json and keep every other key; this
excerpt shows the two objects:
{ "training": { "selection": { "method": "sampled", "forward_passes": 10 } }, "simulation": { "selection": { "method": "sampled", "num_scenarios": 2000 } }}Run the study again into a second output directory, so that the Step 3 results stay available for comparison. The 2000-scenario simulation writes about 10,000 files, roughly 70 MB:
novomodelo run my_first_study --output my_first_study/results-moreThe post-run summary, as an excerpt (the timings vary with the machine):
Training complete in 17.4s (128 iterations, iteration_limit) Lower bound: 1.56023e7 $/stage Upper bound: 1.44899e7 +/- 1.88601e7 $/stage Gap: -7.1% (started at 62.3%) Policy rows: 3840 active / 3840 generatedSimulation complete in 17.0s (2000 scenarios) Completed: 2000 Failed: 0 Expected cost: 1.64438e7 +/- 1.47887e6 (std: 3.37435e7)With these values each iteration’s upper bound is the mean of ten trajectory costs, printed
with their standard deviation, and the gap (-7.1 % at the last iteration) is still an
estimate that moves from iteration to iteration. The expected cost of the 2000 scenarios is
a 95 % confidence interval, 1.64438e7 +/- 1.47887e6, that contains the lower bound, so the two agree
within the sampling noise. The lower bound ends slightly higher than in Step 3, at 1.56023e7,
with ten
cuts added per stage in each iteration (3840 policy rows: 128 iterations, ten cuts for each
of the three stages that receive cuts). An exact gap, and the gap
stopping rule, need enumerated forward selection, which this case’s ten openings per stage do not
admit; Converge to a gap
gives the configuration.
What’s Next
Section titled “What’s Next”You have completed a full SDDP study from case setup to results. The following pages go deeper into how the case is structured and how to interpret the output:
- Case Format — what each input file controls
- Convergence & Diagnostics — how to read Parquet output and assess convergence
- CLI Reference — all flags, subcommands, and exit codes
- Configuration — every
config.jsonfield documented